
What are LoRAs?
A plain-language guide to fine-tuning AI image models
October 5, 2026All Articles
“LoRA” comes up constantly around AI image generation, in model cards, tutorials, community forums, but it rarely gets explained outside an already-technical audience. Here’s what the term actually means: how it works, what it changes, and why some models support it and others don’t.
What does LoRA stand for?
Low-Rank Adaptation. It’s a fine-tuning method, not a model of its own, a way of teaching an already-trained model a specific style, subject, or concept without retraining the whole thing from scratch.
How LoRA fine-tuning works
Training a full image-generation model from nothing takes enormous amounts of data, compute, and time, and produces a file that’s tens of gigabytes. Full fine-tuning, retraining that same base model on new data, isn’t much cheaper: nearly every one of its billions of parameters still gets updated and re-saved.
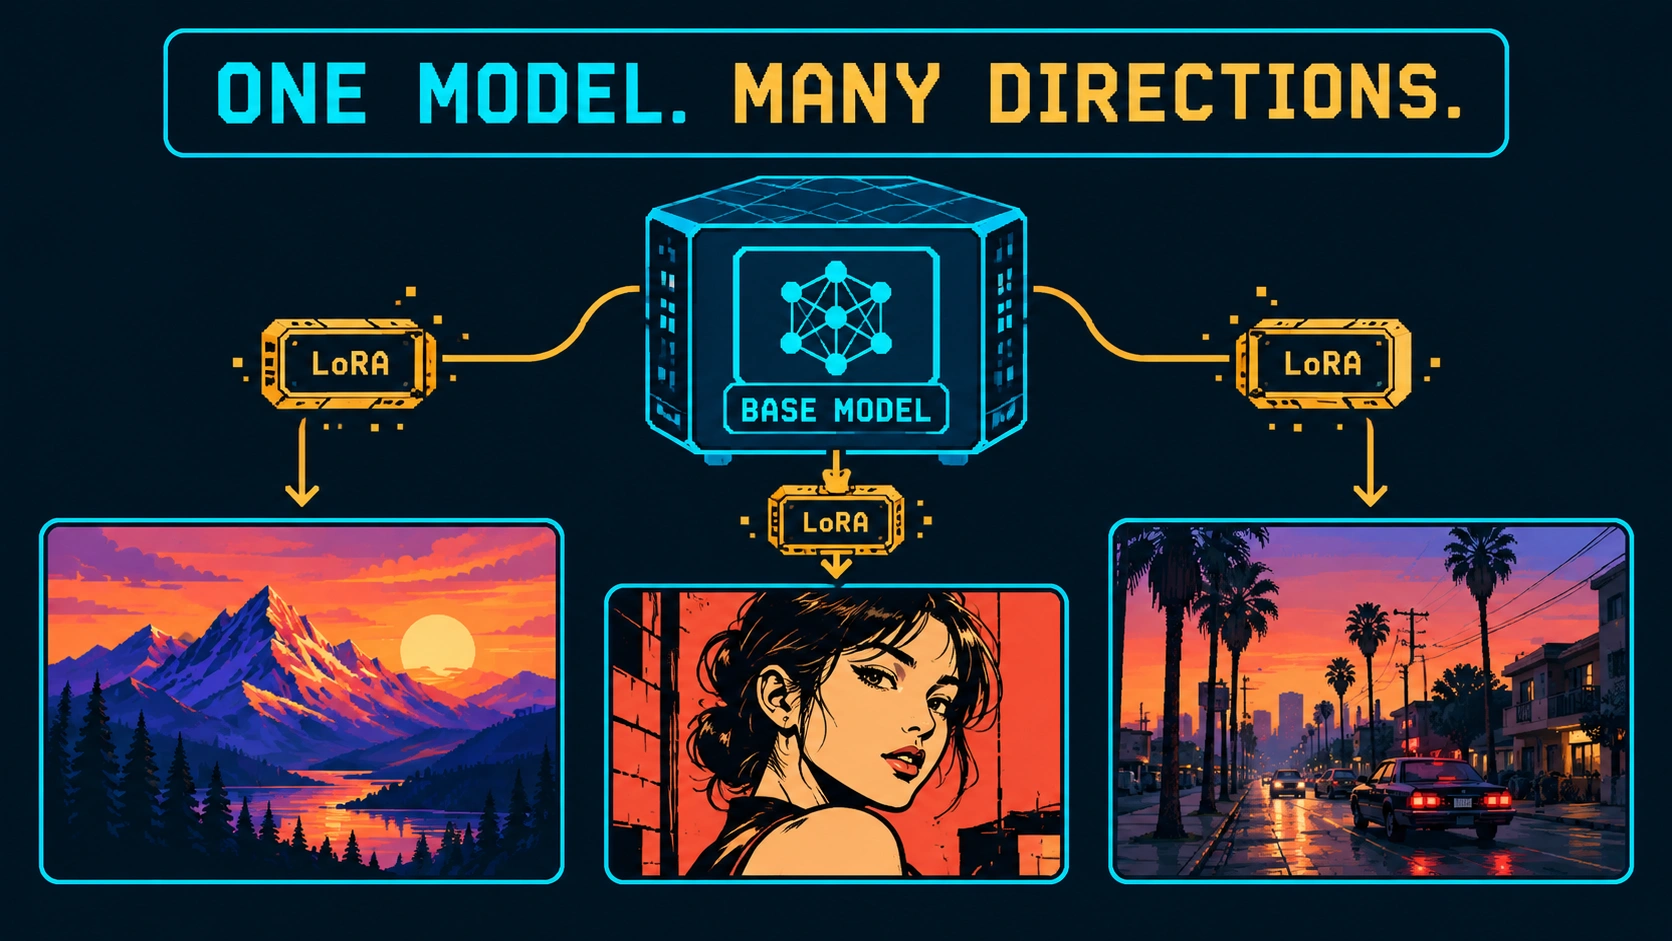
LoRA works differently. The original base model is left frozen and untouched. Instead, small trainable matrices get inserted into specific layers of the model, and only those get trained, a fraction of the parameters a full fine-tune would touch. What comes out the other end is a small adapter file, often tens or hundreds of megabytes rather than gigabytes, that layers on top of the base model at generation time.
What a LoRA actually changes
A LoRA doesn’t replace or retrain the model underneath it, it nudges its output toward something specific. Common uses:
- A particular art style or illustration technique the base model doesn’t produce well on its own
- A consistent character, mascot, or product across many generations
- A specific clothing style, prop, or recurring visual detail
- A regional or genre-specific aesthetic, comic-book inking or a particular era’s photography, for example
Applying different LoRAs to the same base model is how a lot of AI art gets its distinct, repeatable look, the same underlying model doing very different work depending on which adapter is layered on top of it.
Why some models support it and others don’t
LoRA training generally needs a base, undistilled model to work with, not a distilled “Turbo,” “Lightning,” or “Schnell” variant. Distilled models are built around a fixed, minimal-step generation process, which doesn’t leave the same room for the kind of fine-tuning a LoRA depends on. This is why base models tend to get documented as fine-tunable and LoRA-compatible while their faster, distilled counterparts generally don’t, they’re built for different jobs.
Final thoughts
LoRAs are the reason the wider AI art community can push a single base model in dozens of different creative directions without retraining it from the ground up each time. Knowing the term makes model documentation, and a lot of the AI art world, considerably easier to read.
Learn how to get started with the Distinct AI product line-up or explore the rich features built into each product.